The first thing this checklist caught was on my own site. Both blog category pages showed a breadcrumb trail on screen, and neither had the BreadcrumbList markup that should sit behind it. I'd built those templates myself and never noticed, because nothing looked broken.
That's the case for running a checklist in a fixed order instead of from memory. AI search adds a few new failure points to technical SEO: crawlers that don't run JavaScript, separate bots for training and for search, and firewalls that block a bot robots.txt allows. Most of them are invisible from the browser.
This is the checklist I use. It has seven stages and 75 checks. Each check has a pass rule, a way to verify it, and a priority: P0 blocks indexing or AI access, P1 weakens signals, P2 is hygiene. Every stage below also carries the documentation behind its rules and an example from this site, including the rows it fails.
How to work through it
The stages run in order because each one depends on the one before it. Fixing schema on a page an AI crawler can't reach changes nothing, which is the same reason Eligibility is the only hard gate in my R2A Content Framework.
- Work the stages in order, and clear every P0 in a stage before you move to the next.
- Mark each row Pass, Fail or N/A as you go. N/A is a real answer: a personal site has no SoftwareApplication schema to check.
- Run the International module only if the site serves more than one language or region.
- Run two loops. Stages 0 to 5 are the site audit: run them at launch, then once a quarter. Stage 6 is the publish gate: run it on every new or changed URL before it goes live.
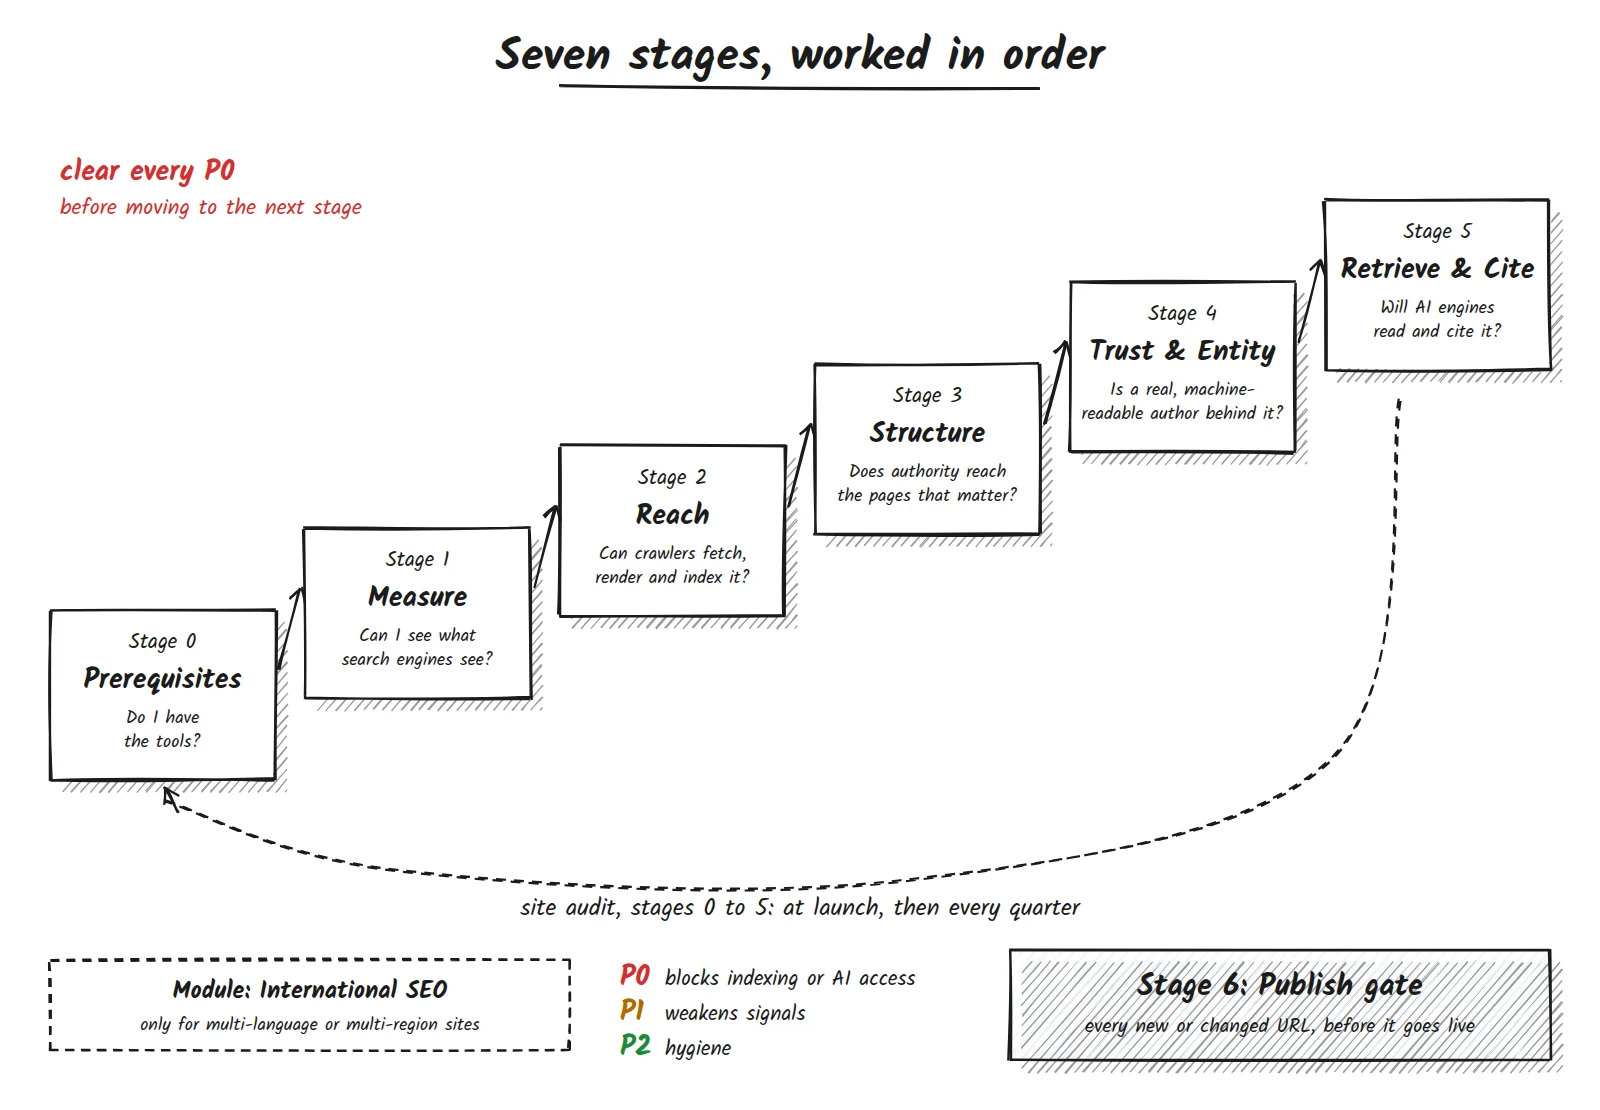
| Stage | The question it answers | What changes for AI search |
|---|---|---|
| 0. Prerequisites | Do I have the tools? | Nothing yet. Without Search Console and a crawler you can't see the rest. |
| 1. Measure | Can I see what search engines see? | Bing matters as much as Google: ChatGPT's web browsing launched on Bing in 2023. |
| 2. Reach | Can crawlers fetch, render and index the right pages? | Many AI crawlers read the raw HTML only, so anything JavaScript adds may never be seen. |
| 3. Structure | Does authority reach the pages that matter, and is each page clear? | Clear headings and one canonical URL per page make passages easier to lift. |
| 4. Trust & Entity | Is a real, machine-readable author behind it? | An engine deciding whose words to repeat looks for a named, consistent identity. |
| 5. Retrieve & Cite | Will AI engines read and cite it? | The right bots allowed, and answers phrased the way buyers ask. |
| 6. Publish gate | Is this new or changed URL ready to go live? | Each page enters the index clean on day one. |
| International | Does each visitor get the right language version? | Conditional: multi-region sites only. |
Stage 0. Prerequisites
Two tools, both P0, because every later stage reads from them.
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| Search Console access | You can open the property for the site you're auditing | Log in and confirm the property shows data | P0 |
| A crawler | A full crawl of the site completes | Screaming Frog's free tier handles up to 500 URLs; start with the issues it ranks highest | P0 |
Stage 1. Measure: can you see what search engines see?
This stage sets the baseline that later results get compared against. On the AI side I add one thing most technical checklists leave out: an LLM referral segment in analytics, which is how I measured the Wellows growth in the first place.
Evidence. Google treats a sitemap as a weak canonical signal, behind redirects and rel="canonical" (Google Search Central), which is why a sitemap that lists redirecting or broken URLs muddies signals instead of just wasting space.
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| Search Console verified | A Domain property is verified and the Performance report shows data | Add the Domain property, verify with a DNS TXT record, wait a day or two for data | P0 |
| Analytics connected | The tag fires in real time and is linked to Search Console; key events are defined once, site-wide | Install through GTM or the page head, then link the two under Associations | P1 |
| Bing Webmaster Tools verified | Bing shows crawl and index data | Import the site from Search Console at bing.com/webmasters | P0 |
| Sitemap submitted and clean | It lists only indexable URLs that return 200, and few submitted URLs go unindexed | Submit it under Indexing, Sitemaps, then compare submitted with indexed | P0 |
| robots.txt leaves key paths open | No Disallow on the blog, product or other revenue directories | Open yoursite.com/robots.txt and read every Disallow line | P0 |
| One host | www and non-www resolve to one version through a site-wide 301 | Request both and check where each lands | P1 |
| HTTPS enforced | http:// requests 301 to https:// at the server | Request the http:// version of a deep URL, not only the homepage | P0 |
| No mixed content | No http:// assets load on https:// pages | Look for mixed-content warnings in the browser console | P2 |
| No manual actions | Search Console reports no issues | Security & Manual Actions in Search Console | P0 |
| Sections in subfolders | The blog and docs live at site.com/blog, not blog.site.com | Keep subdomains for separate products, regions or tech stacks | P2 |
Stage 2. Reach: can crawlers fetch, render and index the page?
This stage holds most of the P0s. If the copy only appears once JavaScript runs, many AI crawlers never see it, which is why the Citeability Checker reads what's in the HTML rather than what a browser paints.
Evidence. Google renders JavaScript in a separate step after crawling (JavaScript SEO basics); crawlers that skip that step only get the HTML. A noindex rule only works if the crawler can fetch the page, so a URL blocked in robots.txt can still appear in results (block indexing). And Google only reliably follows links that are <a> elements with an href, which is why button-driven pagination fails (pagination).
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| Content without JavaScript | The key copy is in the raw HTML | View Source and search for a sentence, or disable JavaScript in DevTools; compare with URL Inspection's crawled page | P0 |
| No noindex on key pages | Neither the meta robots tag nor the X-Robots-Tag header says noindex | Filter the crawl by directives, and check response headers separately | P0 |
| Canonicals correct | Key pages point to themselves, and nothing points to the homepage by mistake | Crawl report of canonical targets | P0 |
| FAQ answers in the source | Answers sit in the HTML, aren't loaded on click, and aren't aria-hidden | View Source and search for one answer | P0 |
| Sitemap only lists 200s | Zero redirecting, broken or noindexed URLs in it | Crawl the sitemap in list mode | P1 |
| No redirect chains | Every redirect lands in one hop | Redirect chain report | P1 |
| Linked dead URLs redirected | Old URLs with backlinks 301 to the closest live page, not the homepage | Broken-backlink report, sorted by referring domains | P1 |
| 404s with value fixed | 404s that still get traffic or links are redirected | Crawl 4xx report, cross-checked with Search Console's Pages report | P1 |
| No soft 404s | Empty pages return a real 404, or carry real content | Search Console Pages report, Soft 404 (usually empty categories and search results) | P1 |
| Site search kept out | /?s= pages are noindexed, disallowed and absent from the sitemap | Check the template, robots.txt and the sitemap | P2 |
| Thin URLs kept out | Tag archives, filters and parameter URLs are noindexed | List the thin URL patterns in the crawl | P2 |
| Pagination uses links | Page 2 is an <a href>, not a button that runs a script |
View Source on a paginated list | P1 |
| Paginated pages self-canonical | Page 2's canonical is page 2, not page 1 | Crawl report of canonical targets | P1 |
For the FAQ row, this is the difference in the markup:
<!-- Fails: the answer isn't in the HTML until someone clicks -->
<button data-faq="12">Do you work with SaaS?</button>
<div class="answer"></div>

<!-- Passes: collapsed for people, present for crawlers -->
<details>
  <summary>Do you work with SaaS?</summary>
  <p>Yes. Most of my in-house work has been B2B SaaS.</p>
</details>
Stage 3. Structure: does authority reach the pages that matter?
Two halves: how pages link to each other, and whether each page is clear on its own. The linking half is where topic cluster architecture does its work, and descriptive anchors are part of what makes a central entity readable across a whole site.
Evidence. Google builds title links from the title element, the main heading, og:title and anchor text pointing at the page, among other sources (title links), and it sets no character limit; long titles are truncated by width on the results page. Breadcrumb markup needs at least two ListItems with a name, an item URL and a position (breadcrumb structured data). Core Web Vitals pass when 75% of page views meet LCP 2.5 s, INP 200 ms and CLS 0.1 (web.dev).
3A. Internal linking
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| Key pages in the nav or footer | Revenue pages are linked site-wide; low-value pages stay out of the nav | Read the nav and footer on three templates | P1 |
| No orphan pages | Every page that matters has at least one internal link in | Orphan report with analytics, Search Console or the sitemap connected to the crawler | P1 |
| Three clicks deep at most | Key pages sit at depth three or less | Crawl depth column | P1 |
| Descriptive anchors | No "click here" or "learn more"; the anchor names the target topic without stuffing | Anchor text export | P2 |
| Breadcrumbs marked up | A visible trail, with BreadcrumbList JSON-LD that matches it | Inspect each template, not just one page | P2 |
| No broken internal links | Zero internal links point to a 4xx | Inlinks to 4xx URLs in the crawl | P1 |
3B. On-page
For titles and descriptions, the SERP Preview shows roughly where Google will cut them off.
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| One H1 per page | No page has two, which is usually a template problem | Crawl report of pages with multiple H1s | P2 |
| No missing H1 | Every product and landing page has a descriptive H1 | Crawl report of pages with no H1 | P1 |
| Unique descriptions | No duplicates on pages that matter, each around 155 characters | Crawl report of duplicate and long descriptions | P2 |
| Unique titles | Every indexable page has its own title, topic first, short enough to show in full | Crawl report of missing, duplicate and over-width titles | P1 |
| Dated titles current | Roundups and listicles show this year in the title, description and headings | An annual pass, only on pages that carry a year | P2 |
| Clean URLs | Lowercase, hyphenated, descriptive and stable; every change is 301'd | /technical-seo-audit passes; /page?id=8842&ref=x fails | P2 |
| One page, one URL | Parameter, filter, trailing-slash and protocol variants consolidate to one | 301s and canonicals; most work on e-commerce sites | P1 |
| Key pages self-canonical | Homepage, product and landing pages are canonical to themselves | Crawl report of canonical targets; stops ?utm_ variants competing | P1 |
| Core Web Vitals pass | LCP 2.5 s or less, INP 200 ms or less, CLS 0.1 or less at the 75th percentile | Search Console's Core Web Vitals report, on mobile and desktop | P2 |
| Speed work done | PageSpeed Insights opportunities are addressed | Serve WebP or AVIF images through a CDN, minify CSS and JS, defer render-blocking files | P2 |
| Mobile parity | The mobile page has the same copy, links and structured data as desktop, and the layout holds at phone, tablet and desktop widths | Lighthouse, or URL Inspection's crawled page | P1 |
| Alt text | Informative images are described; decorative ones use alt="" | Crawl report of images missing alt | P2 |
| Favicon eligible | Square, at least 8x8 px and ideally over 48x48, on a crawlable URL linked from the homepage head (Google) | Load the favicon URL, then check robots.txt doesn't block it | P2 |
Stage 4. Trust & Entity: is a real author behind it?
An engine deciding whose words to repeat needs to know who wrote them. This stage makes that easy: real people on the page, and the same identity in the markup. The Schema Generator gives a clean starting point for the markup half.
Evidence. Google's structured data rules require markup to describe what's visible on the page, and treat markup that doesn't as a policy issue (structured data guidelines). That's the reason for the "values match the visible page" row, and for never adding ratings you can't show.
4A. People and proof
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| Trust pages in the footer | Contact, Terms and Privacy are linked, with current contact details | Read the footer; missing pages are a red flag on money and health topics | P1 |
| Live social links only | No abandoned profiles are linked | A quarterly click-through of every social link | P2 |
| A real About page | It names the team, the history, the customers and why the business exists | Read it as a stranger would | P1 |
| Named authors | Every post has a real author with an author page, never "Admin" or "Team" | Spot-check ten posts | P1 |
| Checkable author boxes | A real photo, a two to three line bio of relevant expertise, and links to LinkedIn, X or a site | Spot-check ten posts | P1 |
| Claims sourced | Statistics and claims link to studies, official data or recognised industry sources | Spot-check posts; another blog's opinion doesn't count as proof | P1 |
4B. Schema
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| Organization on the homepage | JSON-LD with name, logo, sameAs and contactPoint | Rich Results Test on the homepage | P1 |
| SoftwareApplication (SaaS only) | name, applicationCategory and operatingSystem on product pages | Rich Results Test on a product page | P1 |
| BlogPosting on every post | headline, a linked author, datePublished, dateModified and image | Rich Results Test on a sample of posts | P1 |
| BreadcrumbList site-wide | Matches the visible trail on every template | Rich Results Test per template | P2 |
| AggregateRating only from real reviews | Ratings come from G2, Capterra or your own verified reviews | Fabricated ratings risk a manual action | P2 |
| Markup validates | Zero errors in both validators | Rich Results Test and validator.schema.org; errors first, then warnings | P1 |
| Markup matches the page | Recommended fields are filled and every value appears on the page | Read the JSON-LD next to the page copy | P1 |
| Enhancement reports clean | Search Console flags no structured data errors | Fix, then request validation | P1 |
Stage 5. Retrieve & Cite: will AI engines read and cite it?
The shortest stage, and the one where advice most often goes wrong, nearly always on which bots to allow.
Evidence. OpenAI runs GPTBot for training, OAI-SearchBot for ChatGPT search and ChatGPT-User for fetches a person asks for, and each obeys its own robots.txt group (OpenAI). Anthropic splits the same way into ClaudeBot, Claude-SearchBot and Claude-User (Anthropic). Perplexity runs PerplexityBot for its index and Perplexity-User for live fetches, and its own documentation says Perplexity-User generally ignores robots.txt because a person started the request (Perplexity).

| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| AI search and user-fetch bots allowed | No Disallow applies to OAI-SearchBot, ChatGPT-User, Claude-SearchBot, Claude-User, PerplexityBot or Perplexity-User | Read robots.txt group by group, then check the CDN and firewall bot settings | P0 |
| Buyer-phrased FAQs | Questions read the way buyers ask an assistant, such as "How do I get my SaaS cited by ChatGPT?", not "What is SEO?" | Pull questions from sales calls, support tickets and Reddit threads | P1 |
| FAQ answers in the source | Same rule as Stage 2 | View Source | P0 |
| llms.txt at the root | Markdown with the brand as the H1, a one-line summary and grouped links to key pages | Load yoursite.com/llms.txt | P2 |
The Query Fan-Out Generator is where my buyer-phrased questions usually start: it shows the sub-questions an engine generates from one prompt. What makes the answers liftable once they're on the page is in how to get cited by ChatGPT, Gemini and Perplexity.
Stage 6. Publish gate: is this URL ready to go live?
Stages 0 to 5 describe the site. This stage describes one URL on the day it ships, and most rows point back to a site-level rule, so the gate stays short.
Evidence. Google reads both redirects and rel="canonical" as strong signals for which URL is the real one (canonicalization). A URL that moves after launch has to update both, plus every internal link, which is why the slug gets settled before the page ships.
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| Final URL set | The slug is lowercase, hyphenated and in the right section folder, and the canonical points to it | Check against the site's URL map; moving it later costs a 301 and a canonical update | P1 |
| Keyword in title, H1 and URL | The primary keyword is in all three, near the start of the title | View Source | P1 |
| Open Graph tags | og:title, og:description, og:image and og:url are present and the share preview shows the right image | LinkedIn Post Inspector or Facebook's Sharing Debugger | P2 |
| HTML errors fixed | Zero errors in the W3C Nu validator; warnings are optional | validator.w3.org/nu, prioritising unclosed tags and duplicate IDs | P2 |
| Design checked | The layout matches the approved design, with nothing overlapping or shifting | Review at phone, tablet and desktop widths | P1 |
| Site rules hold for this URL | 200 status, content in raw HTML, self-canonical, valid structured data, Core Web Vitals, mobile parity, alt text and no broken links | Run each of those rows on this one URL | P0 |
| Staging protections removed | No noindex or nofollow carried over from staging, while staging itself stays protected | View Source and the response headers on the live URL | P0 |
| Page events fire | CTA clicks and form submits on this page reach analytics | Tag Manager preview plus analytics debug view | P1 |
| In the sitemap and requested | The URL is in the sitemap, and URL Inspection shows it indexed or requested | Search Console, URL Inspection, Request indexing | P0 |
Module: International SEO (multi-region sites only)
Evidence. Every language version has to list every other version, itself included, or Google may ignore the annotations (localized versions).
| Check | Pass when | How to verify | Priority |
|---|---|---|---|
| Language subfolders | /en/, /de/, /fr/ on one domain | Subdomains only when required; ccTLDs only for genuinely separate markets | P1 |
| Hreflang complete | Every version lists every version, itself included, with valid codes, in both directions | Hreflang report in the crawler | P0 |
| x-default set | It points to the global or primary version | Hreflang report in the crawler | P1 |
| html lang matches | lang="de" on pages marked hreflang="de" | Language report in the crawler; low impact on its own | P2 |
Six things most technical SEO checklists get wrong
Each ends with how sure I am. Verified means I checked the primary documentation, Secondary means trade press only, and Inferred means it follows from how the systems work but I haven't seen it documented.
1. They treat "AI bots" as one bot. Blocking GPTBot to stay out of training is a reasonable choice, and it doesn't touch citations. Blocking OAI-SearchBot does: OpenAI says sites that opt out of it won't be shown in ChatGPT search answers. The same split exists at Anthropic and Perplexity, as Figure 2 shows. Verified (OpenAI, Anthropic, Perplexity).
2. They rank llms.txt too high. llms.txt is cheap to add, so add it, and treat it as P2. It never outranks crawler access or content in the raw HTML. My judgement, not a documented rule.
3. They still promise FAQ rich results. Google limited FAQ rich results to well-known government and health sites in August 2023, and trade press reports it stopped showing them for all sites in May 2026. FAQ content in the raw HTML still helps AI extraction, so keep the content and drop the expectation of a results-page feature. Verified for 2023 (Google Search Central); Secondary for 2026.
4. They stop at robots.txt. robots.txt can allow a bot while a CDN or firewall rule blocks it, and the robots.txt check passes anyway. The fix depends on the vendor: Perplexity publishes its crawler IP ranges, so you can allowlist them, while Anthropic says it doesn't publish IP ranges and that IP blocking may not work as an opt-out. Verified for the vendor policies (Perplexity, Anthropic); Inferred for how often it happens. Confirm in your CDN dashboard and access logs.

5. They end at implementation. A checklist with no outcome metric can't tell you whether any of it worked. I add a measurement step: track citations and mentions per engine (ChatGPT, Perplexity, Gemini, AI Overviews) before and after the fixes. The BERAP Map is how I measure the recall side of that. Inferred.
6. They carry checks that outlived their tools. FID stopped being a Core Web Vital when INP replaced it on 12 March 2024. Google retired the Mobile-Friendly Test and the Mobile Usability report on 1 December 2023, so mobile checks now run through Lighthouse and URL Inspection. And "keep titles under 60 characters" is a display guide, not a Google rule: Google sets no limit and truncates by width. Verified (web.dev, Google Search Central, title links).
I ran it on this site
A checklist is easier to trust once you've seen it fail something. I ran every row I could check from this site's own build against khadijazaman.com on 2 October 2026. The rows that need live access, such as Search Console, Bing, HTTPS redirects and CDN rules, aren't in this run.

The run is the examples above in one place: a breadcrumb gap fixed in five lines, ten long descriptions rewritten, and three robots.txt groups added for readability rather than access. The build itself is written up in built for two readers.
If you want this run on one of your own pages, the free AI-search access check covers the Stage 2 and Stage 5 rows that decide whether AI search can reach and cite it.
Frequently asked questions
Should I block GPTBot to stay out of AI training?
You can. GPTBot is OpenAI's training crawler, so blocking it affects training only. ChatGPT search uses OAI-SearchBot, and OpenAI says sites that opt out of OAI-SearchBot won't be shown in ChatGPT search answers, so leave that one allowed if you want to be cited.
Does llms.txt help a site get cited by AI?
There's no confirmed evidence that it does. I keep llms.txt at P2: it's cheap to add and harmless, but I don't treat it as a citation lever, and it never outranks crawler access or content in the raw HTML.
Is FAQ schema still worth adding?
Not for rich results. Google limited FAQ rich results to well-known government and health sites in August 2023. Keep the FAQ content itself in the raw HTML, because that still helps AI systems extract answers.
Read next
Built for Two Readers: Why Every Machine Layer on This Site Is Generated From the Page
The build behind khadijazaman.com: Eleventy, a Git-backed CMS, and markdown twins, answers.json, CSP and lastmod all generated from the rendered page.
Read the post →How to Get Your Brand Cited by ChatGPT, Gemini and Perplexity
Ranking #1 in Google no longer guarantees you appear in an AI answer — the systems judge content differently. A checklist to make pages retrieval-ready.
Read the post →